On this page
Nobody outside Perplexity knows how its ranking system is weighted. Perplexity has not published one, and no study has measured one. What you can rely on is shorter. Perplexity has documented how it crawls and retrieves pages, independent studies have measured which sources it cites, and a peer-reviewed paper has tested which edits make content more visible in AI answers. This guide covers those three things, labels each claim as documented or observed, and turns them into a checklist.
A word on what has changed since the first version of this guide. Earlier drafts, ours included, repeated percentage weights for Perplexity's ranking factors, a 5 billion URL index with Bing as a fallback, and fixed rules such as refreshing pages every 2 to 3 days. None of these holds up against a primary source, so they are gone.
Key takeaway: Perplexity runs its own web index, ranks passages rather than whole pages, and only cites pages its crawler can reach. Make sure PerplexityBot can reach you, write sections that answer on their own, back claims with sources and figures, and earn mentions on the third-party sites Perplexity already cites. Then measure with repeated prompts, because the answers change from one run to the next.
What Perplexity documents about how it finds and ranks pages
Perplexity retrieves from its own index and ranks fragments of pages, not entire documents. When it launched its Search API in September 2025, the company said its index covers hundreds of billions of web pages, processes tens of thousands of updates every second, and returns fine-grained, pre-ranked snippets instead of full documents. Coverage of the same launch by InfoWorld describes documents being divided into sub-units that are each scored against the query.
Three practical consequences follow from that design:
- Your page competes paragraph by paragraph. A single well-written section can be retrieved even if the rest of the page is about something else, and a strong page can be skipped if no single passage answers the question.
- Freshness is an engineering goal. Perplexity says its index takes continuous updates. That does not tell you how often your own page is recrawled, and Perplexity publishes no schedule for it.
- There is no official mention of Bing. Perplexity describes its own index and crawler. The claim that it falls back on Bing does not appear in its documentation.
For scale: CEO Aravind Srinivas said at Bloomberg's Tech Summit on June 5, 2025 that Perplexity handled 780 million queries in May 2025, with growth above 20% month over month. Perplexity has not published an official monthly active user count, so figures you see quoted vary widely and come from third parties.
In short: Perplexity ranks pre-scored fragments of pages from its own index of hundreds of billions of pages, not whole documents, so each paragraph competes on its own. Its documentation mentions no Bing fallback and publishes no recrawl schedule.
PerplexityBot and Perplexity-User: what your robots.txt controls
Perplexity documents two user agents, and they behave differently with robots.txt. According to Perplexity's crawler documentation:
| User agent | What it does | robots.txt | Used for model training |
|---|---|---|---|
| PerplexityBot | Crawls the web to surface and link sites in Perplexity search results | Respected | No, per Perplexity |
| Perplexity-User | Fetches a page when a user's request needs it | Generally ignored, because a user asked for the page | No, per Perplexity |
The decision that matters is PerplexityBot. If your robots.txt disallows it, you are opting out of the crawler that feeds Perplexity's search results. Perplexity publishes the IP ranges of both agents (perplexitybot.json and perplexity-user.json) so you can verify that traffic claiming to be Perplexity really is. A minimal rule that keeps the index crawler in looks like this:
User-agent: PerplexityBot
Allow: /
Also check the layers above robots.txt. A CDN or firewall rule that blocks AI bots by default will stop PerplexityBot even when robots.txt allows it. Our AI crawler checker tests both layers for a URL.
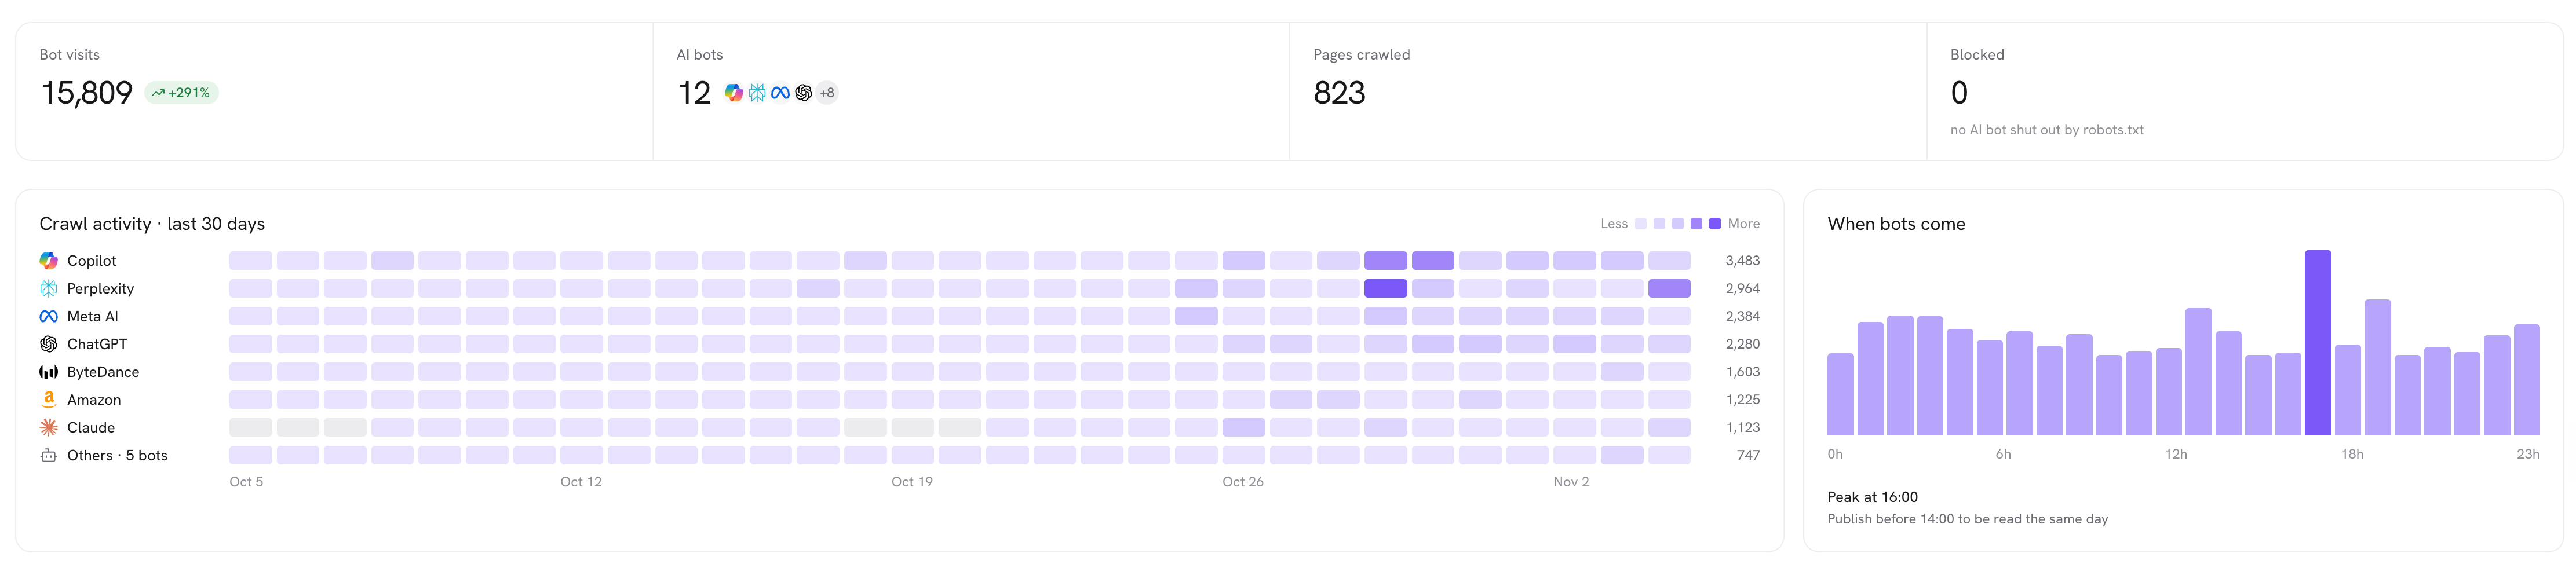
What an open door looks like in Citeme: Perplexity's bots made 2,964 visits to this site in 30 days, and no AI bot was shut out by robots.txt.
One caveat on trust. In August 2025, Cloudflare accused Perplexity of using undeclared crawlers to reach sites that had blocked its declared bots. Perplexity rejected the analysis. The dispute does not change the practical advice: if you want to be cited, allow PerplexityBot.
In short: PerplexityBot crawls the web for Perplexity search results and respects robots.txt, while Perplexity-User fetches pages on user request and generally ignores it; Perplexity says neither is used for training. To be cited, allow PerplexityBot in robots.txt, the CDN and the firewall.
What citation studies observe
Studies of Perplexity's citations agree on one pattern: it leans heavily on community and third-party sources. These are observations from large samples, not rules Perplexity has stated.
Reddit dominates the most-cited domains
Profound analyzed 680 million citations collected between August 2024 and June 2025 and published the results on June 5, 2025. On Perplexity, Reddit accounted for 6.6% of all citations and 46.7% of the citations going to its 10 most-cited domains, followed by YouTube, Gartner, Yelp and LinkedIn. The lesson is not to post on Reddit at any cost. It is that for many questions, the page Perplexity cites about your brand is not yours, so what others write about you counts as much as your own site.
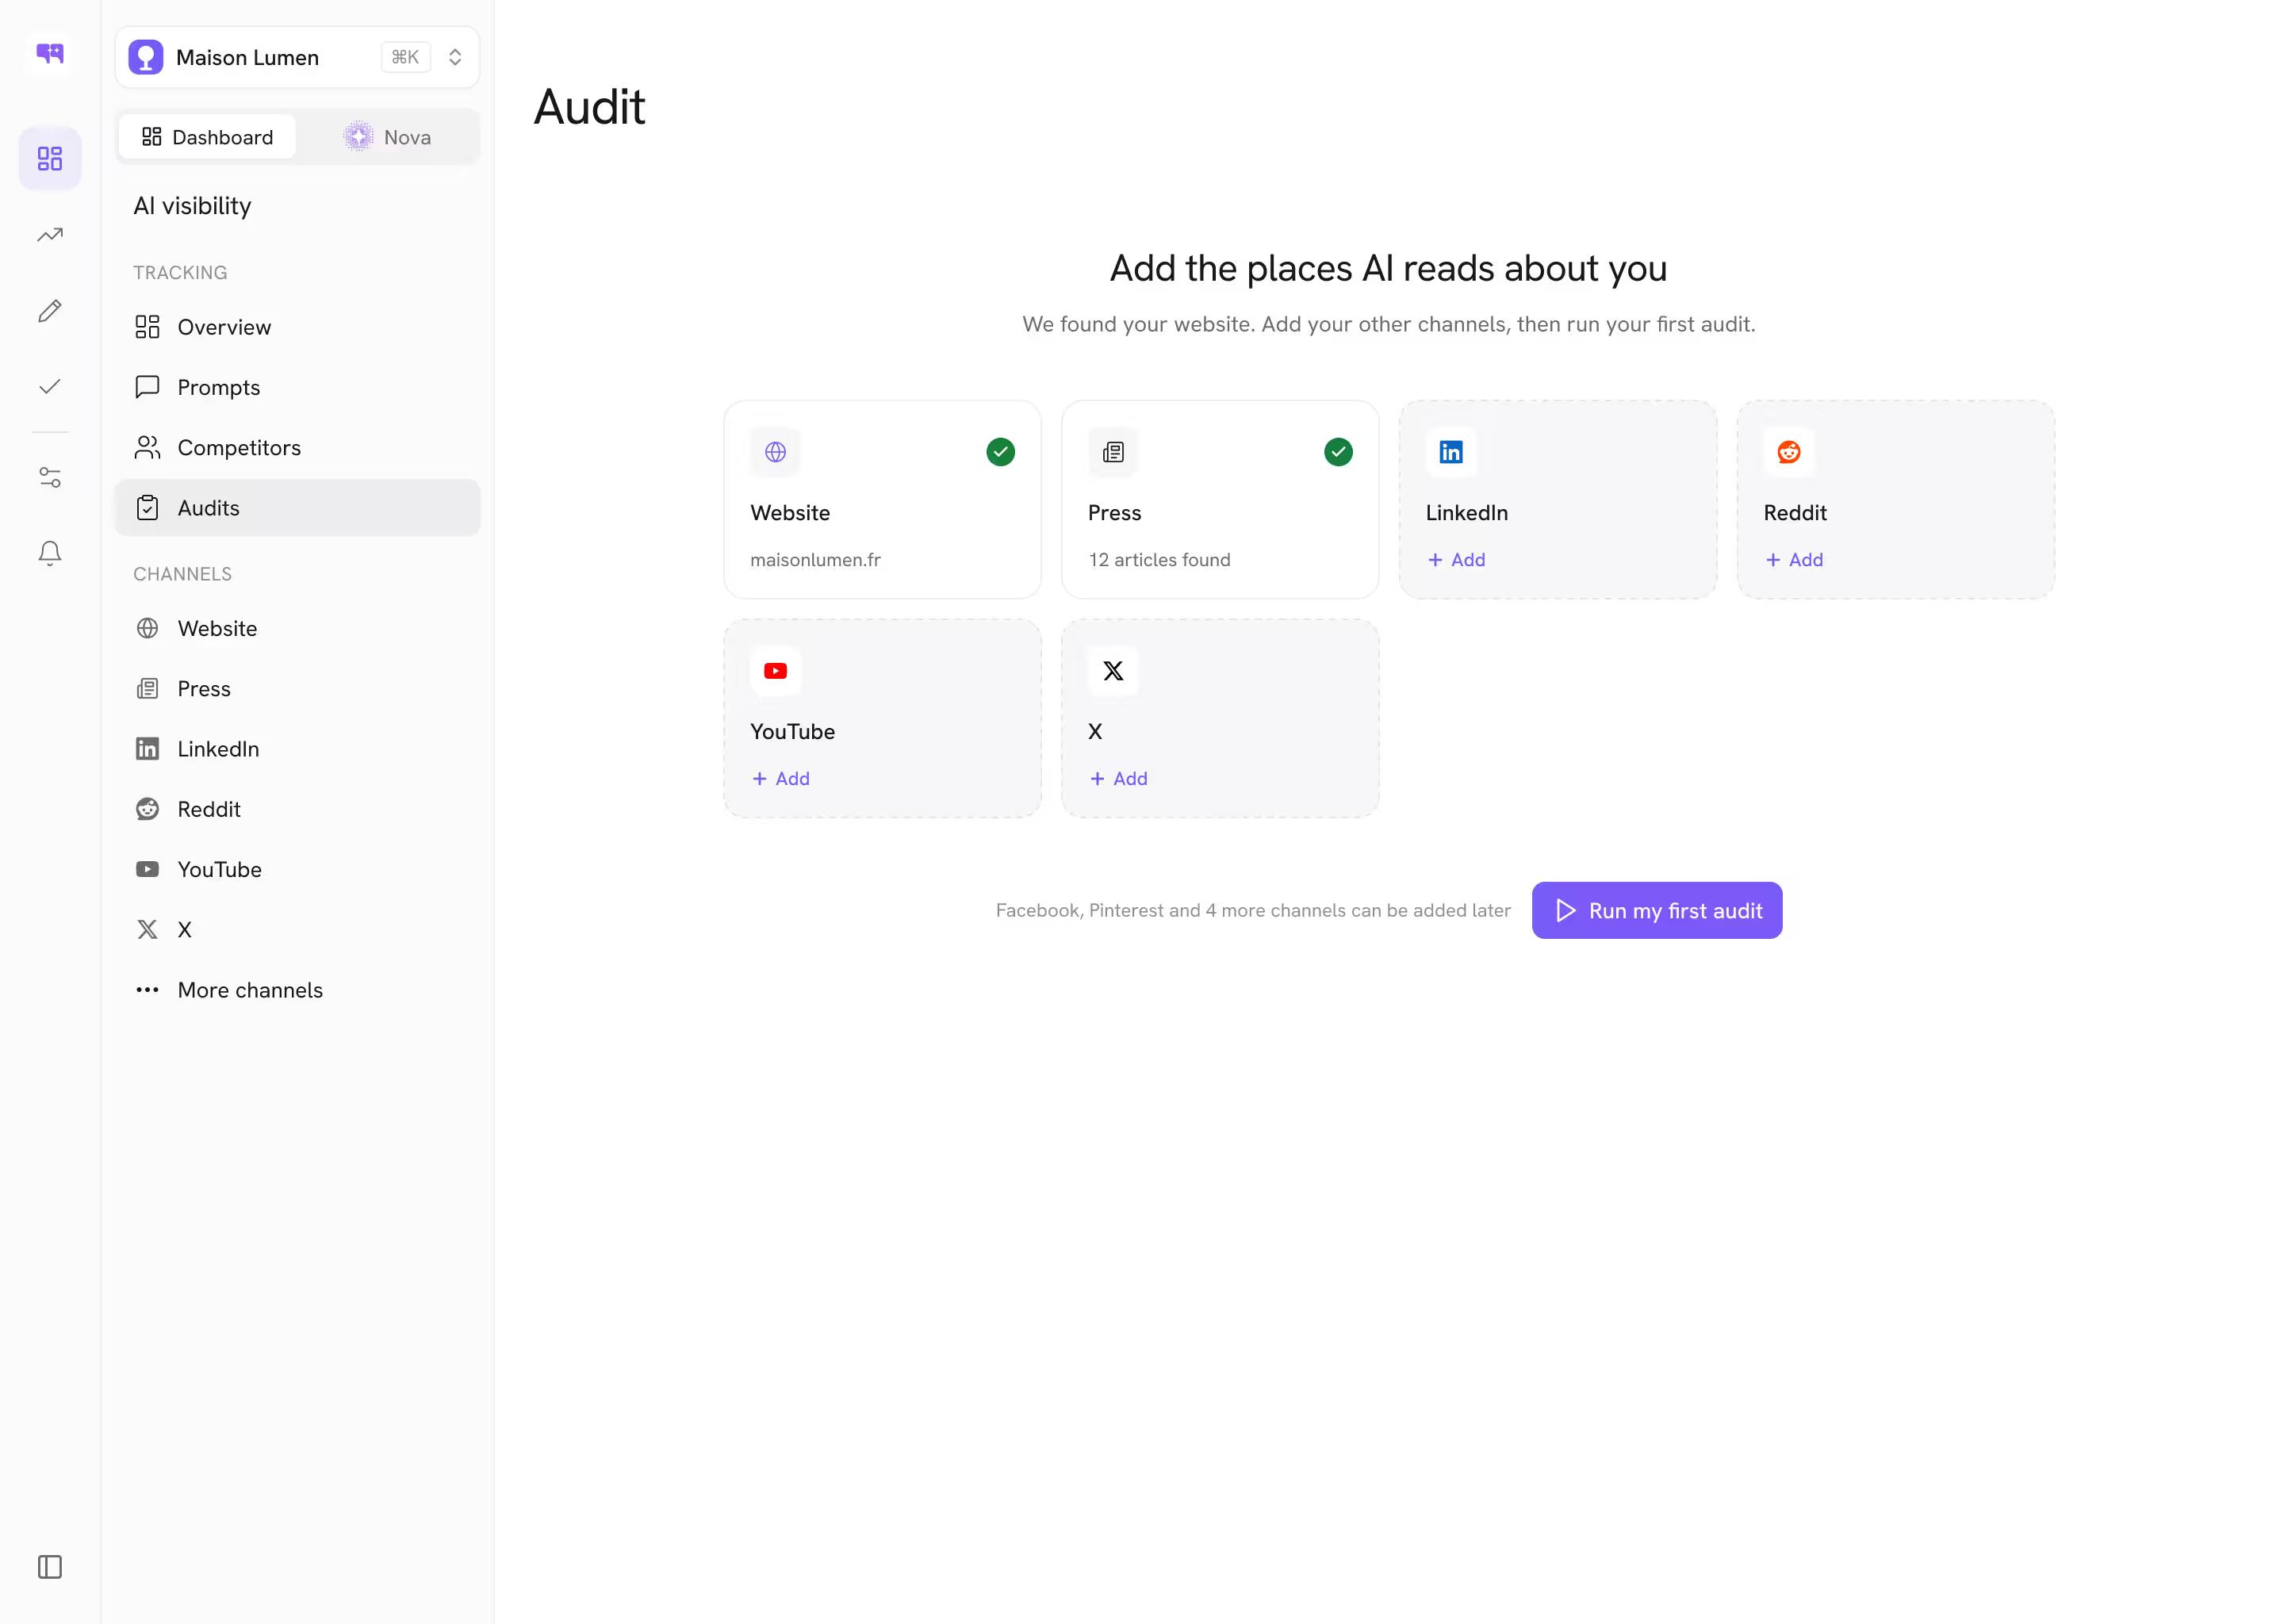
Because Perplexity leans on Reddit, YouTube and LinkedIn, a Citeme audit covers those channels next to the website. Demo data (Maison Lumen).
Freshness helps at the margin, and order follows recency
In a study of about 17 million citations from AI assistants and Google, published in July 2025, Ahrefs found that the pages AI assistants cite are about 25.7% fresher than those ranking in Google's organic results, and Perplexity appears to order its citations from newer to older. But the average page Perplexity cites was still 1,166 days old. Updating a page with new facts is worth doing. A fixed refresh cycle of a few days is not supported by any of this data, and Ahrefs warns that frequent updates to weak content will not help.
Answers are unstable
SparkToro found that AI assistants rarely return the same list of brands twice for the same prompt. A single check on Perplexity tells you very little. You need repeated runs before you can read a trend.
In short: Citation studies show Perplexity leans on third-party sources: Reddit took 6.6% of its citations in Profound's analysis of 680 million citations, Ahrefs found AI-cited pages 25.7% fresher than Google results, and SparkToro found brand lists rarely repeat.
What the GEO paper shows
The only peer-reviewed evidence on which edits raise visibility in AI answers comes from the GEO paper presented at KDD 2024. The authors rewrote source pages in several ways and measured how much of each page made it into the generated answer.
- What worked: adding quotations from relevant sources, adding statistics, and citing sources. On their benchmark, the best methods raised visibility by up to about 40%.
- Tested on Perplexity: the authors also ran their methods on Perplexity.ai. Quotation addition improved the position-adjusted word count by about 22%, and statistics addition improved the subjective impression score by about 37%.
- What failed: keyword stuffing did little or worse than nothing, including on Perplexity, where it came out about 10% below the baseline.
- Who gains most: lower-ranked sources gained the most. Citing sources raised the visibility of the source ranked fifth by 115%, while top-ranked sources sometimes lost visibility.
Keep the limits in mind. The experiments rewrote pages that had already been retrieved, so they say nothing about getting into the candidate set in the first place, and Perplexity's system has changed since 2023. The direction is still clear: verifiable facts beat keyword density.
In short: The GEO paper presented at KDD 2024 found that adding quotations, statistics and cited sources raised visibility in AI answers by up to about 40%, including on Perplexity, where keyword stuffing scored about 10% below the baseline.
Claims to treat with caution
Much of what circulates about Perplexity ranking comes from reverse engineering that nobody else has reproduced. The best-known example is researcher Metehan Yesilyurt's 2025 analysis, covered by Search Engine Land. It describes an L3 machine-learning reranker, manually curated lists of authoritative domains, topic multipliers and a time-decay factor, all inferred from parameters observed in the browser. It is interesting, but it is not documentation, and it gives no weights.
| Claim | Status | What we can say |
|---|---|---|
| Own index of hundreds of billions of pages, passage-level ranking | Documented by Perplexity | Write sections that stand on their own |
| PerplexityBot respects robots.txt, Perplexity-User generally does not | Documented by Perplexity | Allow PerplexityBot if you want to be cited |
| Reddit and other third-party sites take a large share of citations | Observed (Profound) | Work on off-site mentions, not only your pages |
| Cited pages are fresher than Google results | Observed (Ahrefs) | Update facts and dates when they change |
| Statistics, quotations and cited sources raise visibility | Measured (GEO paper) | Back each key claim with a sourced figure |
| Reranker, authority lists, topic multipliers | Reverse engineered, not confirmed | Plausible, but do not plan around it |
| Percentage weights per ranking factor | No known source | Ignore |
| Bing as a fallback index, 5 billion URLs | Contradicted by Perplexity's own statements | Ignore |
| Refresh every 2 to 3 days, sub-200 ms server response | No known source | Ignore the thresholds; keep pages fast and current |
Schema markup is also in this gray zone. Perplexity has published nothing saying it reads structured data for ranking, and Google withdrew FAQ rich results on May 7, 2026. Clean markup does no harm, but do not expect it to earn a Perplexity citation by itself.
In short: Perplexity ranking claims such as an L3 reranker, curated authority lists and topic multipliers come from unconfirmed reverse engineering, the Bing fallback is contradicted by Perplexity, and factor weights or a 2 to 3 day refresh cycle have no known source.
A practical checklist
Each step below rests on one of the facts or observations above.
- Open the door. Check that robots.txt, your CDN and your firewall all let PerplexityBot through, and that key content is in the HTML rather than behind a login or loaded only by JavaScript.
- Write sections that answer on their own. Because Perplexity ranks passages, open each section with a direct answer in one or two sentences, with the subject named instead of "it" or "this tool".
- Back claims with sources and figures. Add dated statistics, quotations and links to primary sources. This is what the GEO paper measured, including on Perplexity.
- Keep facts current. Update prices, numbers and dates when they change, and show the update date. Skip cosmetic edits.
- Earn third-party mentions. Find which domains Perplexity cites for your key questions, often Reddit, YouTube, review sites and industry analysts, and make sure your brand is described accurately there.
- Drop keyword stuffing. It did not help in any test in the GEO paper.
- Measure with repeated prompts. Track a fixed set of buyer questions over time, run each one several times, and read the trend rather than a single result.
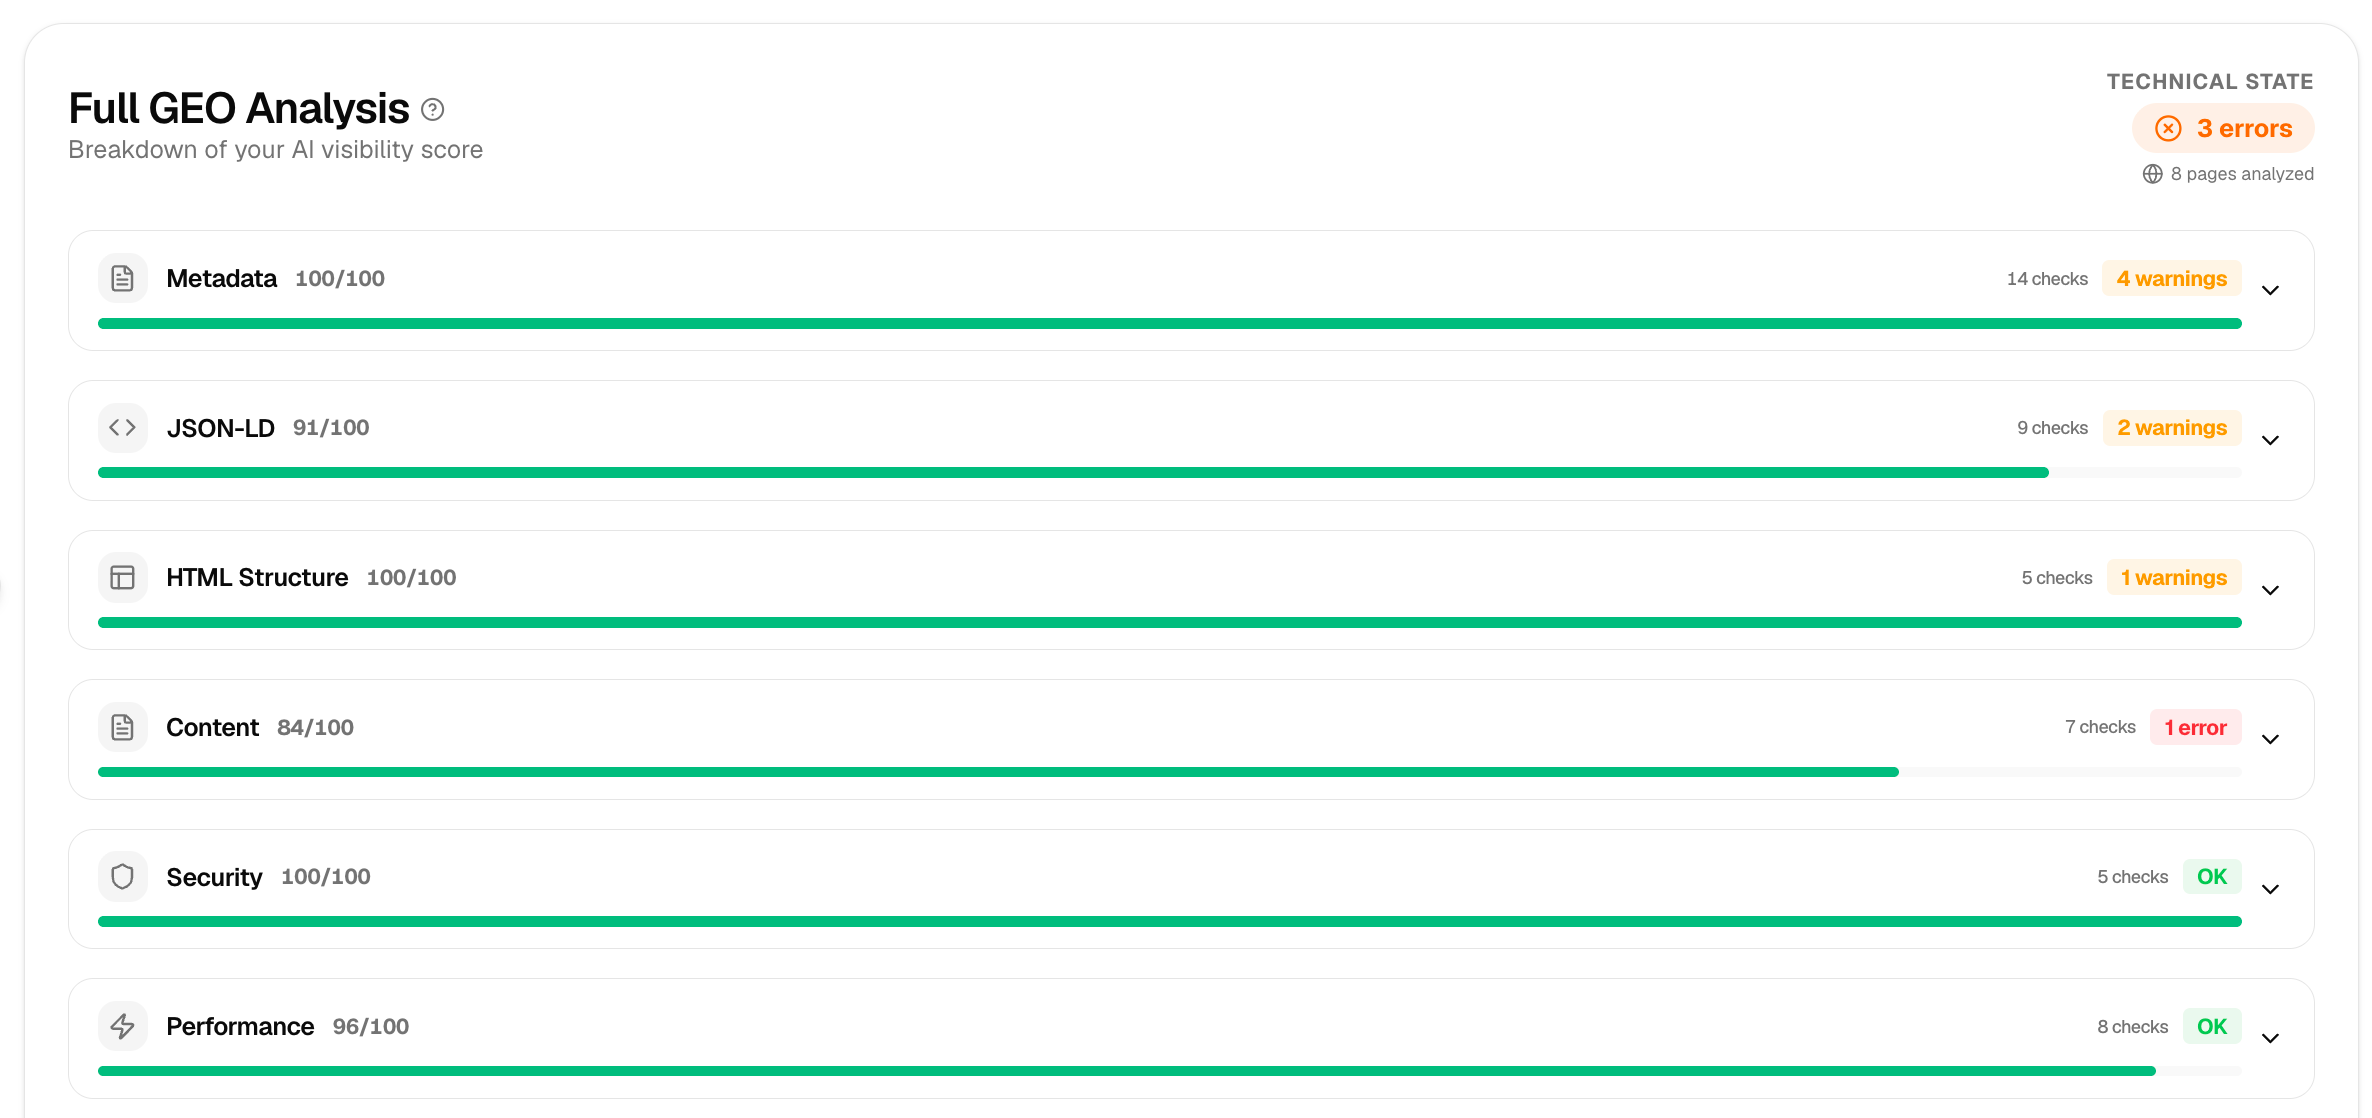
The technical steps of this checklist map to the checks of a Citeme audit, here run on 8 pages with 3 errors to fix.
Most of this list applies to ChatGPT, Gemini and Google AI Overviews as well. For the differences, see our guide on how to rank in ChatGPT and our comparison of AEO, GEO and SEO.
In short: To rank on Perplexity, let PerplexityBot through robots.txt, CDN and firewall, open each section with a direct answer, back claims with dated figures and sources, keep facts current, earn third-party mentions, drop keyword stuffing and measure with repeated prompts.
How to track your Perplexity visibility
Track citation share, not rank: how often Perplexity cites or mentions your brand across the questions your buyers ask, and which domains it cites instead. Build a list of real prompts, run them on a schedule, and log the brands and URLs in each answer. Because answers vary, a trend over several weeks is the useful signal.
You can do this by hand for a dozen prompts. Beyond that, a tracking tool saves time. Citeme, which is our tool, follows 10 engines including Perplexity, measures share of voice against your competitors through competitive monitoring, and shows in its Analytics which AI bots visit your site. It is the tool we recommend for this job, because its agent, Nova, also drafts the fixes and publishes them after your approval; plans start at $69 a month with a 3-day trial for $1 (see pricing). Other tools such as Peec AI, Otterly.AI, Semrush and Ahrefs Brand Radar also cover Perplexity, which is useful if you already pay for one of them. To check a single page first, the free AI citability checker flags passages that are hard for an AI to quote.
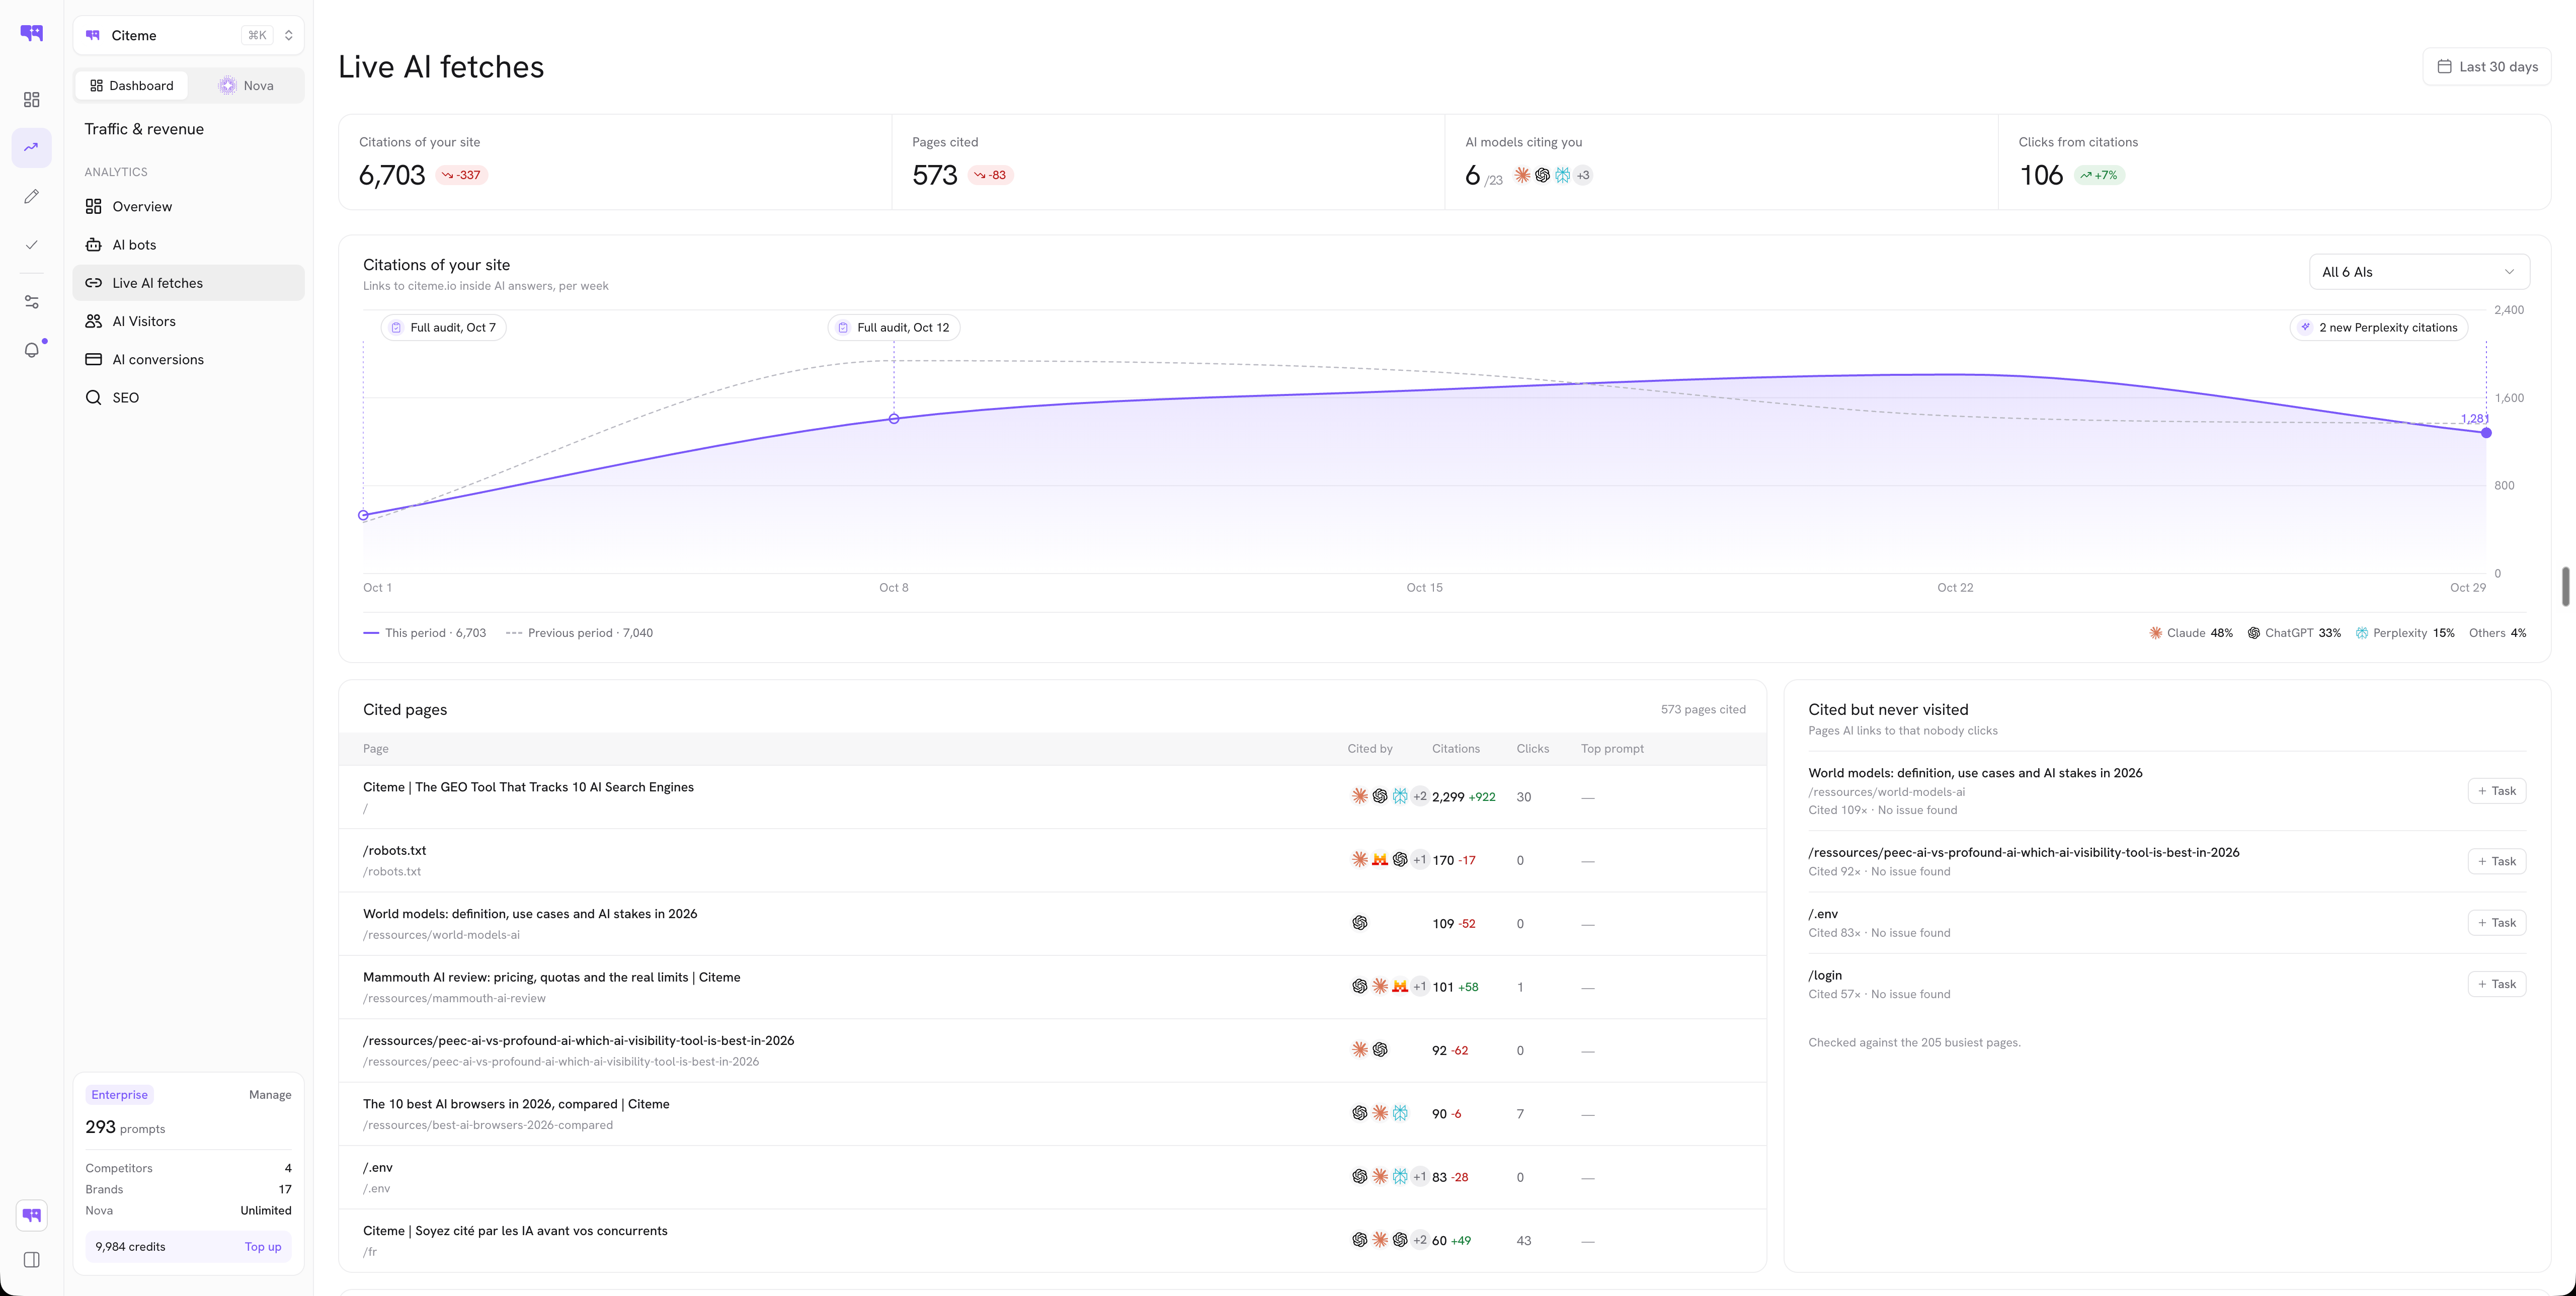
Our own site in Citeme: over 30 days, Perplexity accounted for 15% of the links to citeme.io inside AI answers, and the table shows which pages it cited.
In short: Perplexity visibility is tracked as citation share, not rank: run a fixed list of buyer prompts on a schedule, log the brands and URLs in each answer and read the trend over several weeks. Citeme, our product, tracks Perplexity among 10 engines.
FAQ
How do you rank on Perplexity AI in 2026?
There is no published ranking formula, so focus on what is documented and measured. Allow PerplexityBot in robots.txt and in your CDN rules, write sections that answer a question on their own, back claims with dated statistics and cited sources, keep facts current, and earn accurate mentions on the third-party sites Perplexity already cites, such as Reddit and review sites.
What are Perplexity's ranking factors?
Perplexity has not published them. It has documented that it uses its own index of hundreds of billions of pages and ranks fragments of pages rather than whole documents. Reverse-engineering work describes a machine-learning reranker, authority lists, topic multipliers and time decay, but these are unconfirmed, and percentage weights quoted online have no known source.
Should I block PerplexityBot or Perplexity-User?
If you want to be cited, do not block PerplexityBot: it is the crawler that surfaces and links sites in Perplexity search results, and it respects robots.txt. Perplexity-User fetches pages when a user asks for them and generally ignores robots.txt. Perplexity says neither agent collects content to train foundation models.
Does Perplexity use Bing?
Perplexity's documentation does not mention Bing. The company describes its own crawler, PerplexityBot, and its own index, which it said in September 2025 covers hundreds of billions of web pages and takes tens of thousands of updates per second.
How often should I update content for Perplexity?
Update when the facts change, not on a fixed cycle. Ahrefs found that AI assistants cite pages about 25.7% fresher than Google's organic results and that Perplexity orders citations from newer to older, yet the average page Perplexity cited was still more than three years old. No public data supports a refresh every few days.
Why does Perplexity cite Reddit so often?
Profound's analysis of 680 million citations found that Reddit accounted for 6.6% of all Perplexity citations and 46.7% of the citations going to its 10 most-cited domains. Perplexity has not explained why. In practice, it means community discussions about your category shape answers, so how your brand is described there matters.
Sources (8)
- 1Perplexity Crawlers
- 2Perplexity launches Search API
- 3Perplexity received 780 million queries last month, CEO says
- 4AI Platform Citation Patterns
- 5New Study: AI Assistants Prefer to Cite Fresher Content (17 Million Citations Analyzed)
- 6GEO: Generative Engine Optimization (KDD 2024)
- 7AIs are highly inconsistent when recommending brands or products
- 8Perplexity is using stealth, undeclared crawlers to evade website no-crawl directives
Written by
Maël Bourdin · CTO, CitemeCo-founder of Citeme. He helps brands become visible inside ChatGPT, Claude, Gemini and Perplexity answers through GEO.